Chunking Strategies and Embeddings for Better RAG
Retrieval quality is set by chunking and search, not the prompt. Compares chunking strategies, text embeddings, hybrid search, reranking and measuring recall.
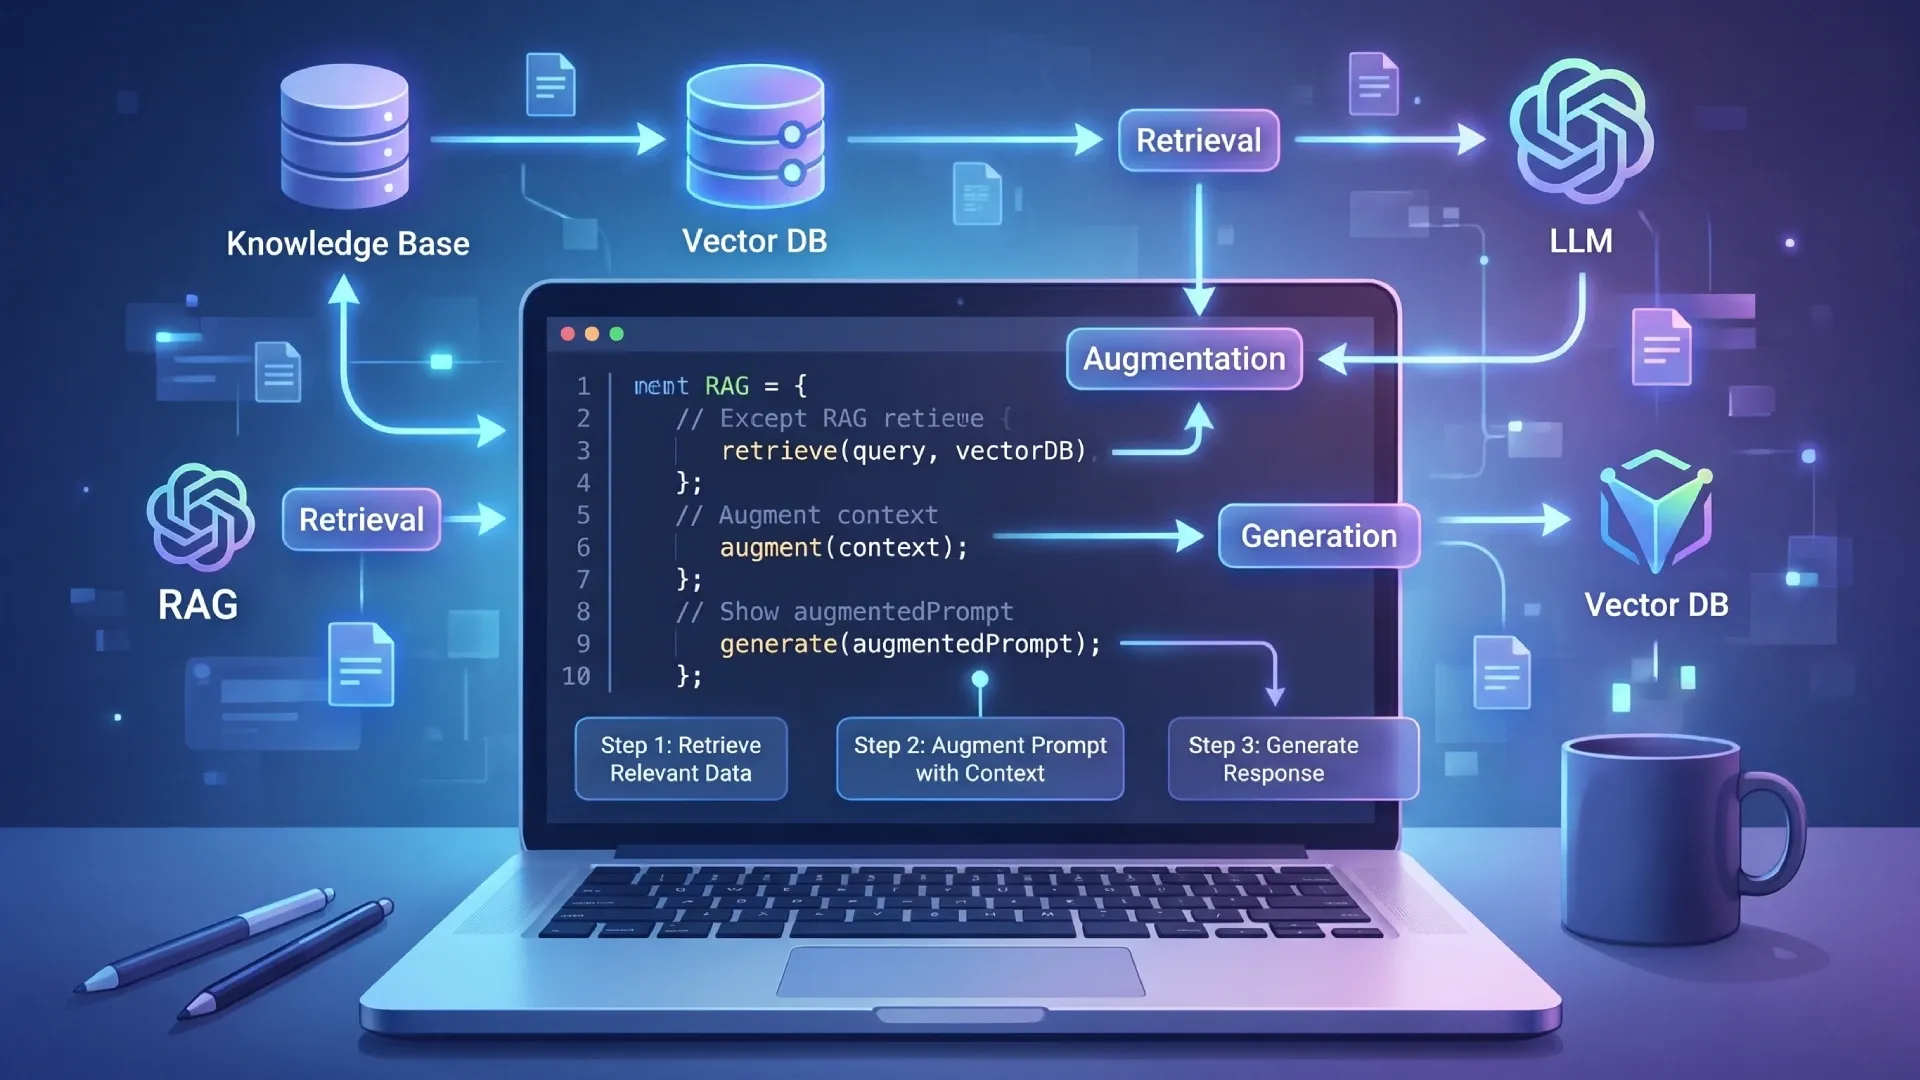
When a retrieval system returns the wrong passage, the fix people reach for is a better prompt or a bigger model. Neither helps. If the right text was never retrieved, nothing downstream can recover it, and retrieval quality is decided almost entirely by two things: how you split the documents, and how you search the resulting vectors.
This is the layer underneath a RAG pipeline, and it is where the largest quality gains are available.
What is an embedding, actually?
An embedding model reads a piece of text and returns a fixed-length list of numbers, typically several hundred to a few thousand of them. Text with similar meaning produces vectors that point in similar directions, which is what makes it possible to search by meaning instead of by keyword.
Similarity is almost always cosine similarity: the angle between two vectors, ignoring their length. Two texts about the same subject score near 1, unrelated texts near 0.
Which model to embed with is a question with a public answer rather than a matter of taste. The MTEB leaderboard ranks embedding models across retrieval, clustering and reranking tasks, and it is the right place to start rather than the first model in whichever tutorial you read. Filter it by the retrieval column, then by dimension count, because a 3,072-dimension vector costs real storage and query time over millions of chunks.
function cosineSimilarity(a: number[], b: number[]): number {
  let dot = 0;
  let normA = 0;
  let normB = 0;

  for (let i = 0; i < a.length; i++) {
    dot += a[i] * b[i];
    normA += a[i] * a[i];
    normB += b[i] * b[i];
  }

  return dot / (Math.sqrt(normA) * Math.sqrt(normB));
}
You will rarely write that, because the database does it. It is worth seeing once, because it makes clear that the whole mechanism is a geometric comparison with no understanding of your domain in it.
Chunking strategies are the highest-leverage decision
A chunk is the unit of retrieval. Whatever you retrieve is what the model sees, so a chunk needs to be small enough to be specific and large enough to make sense on its own. Those pull in opposite directions, which is why this is a real decision rather than a default.
Why does fixed-size chunking underperform?
// The version in every quickstart.
function fixedChunks(text: string, size = 1000, overlap = 200): string[] {
  const out: string[] = [];
  for (let i = 0; i < text.length; i += size - overlap) {
    out.push(text.slice(i, i + size));
  }
  return out;
}
It is simple, predictable, and it cuts through the middle of sentences, splits tables from their headers, and separates "the following three conditions apply" from the three conditions. Every one of those produces a chunk that embeds poorly, because half a thought has an ambiguous meaning.
Structure-aware chunking
Documents already tell you where the boundaries are. Headings, sections, paragraphs. Splitting on those and only falling back to character counts when a section is genuinely too long produces chunks that are coherent by construction.
type Chunk = { text: string; heading: string };

function chunkMarkdown(markdown: string, maxChars = 1200): Chunk[] {
  const sections = markdown.split(/^(?=#{1,3} )/m);
  const chunks: Chunk[] = [];

  for (const section of sections) {
    const heading = section.match(/^#{1,3} (.+)$/m)?.[1] ?? '';

    if (section.length <= maxChars) {
      chunks.push({ text: section.trim(), heading });
      continue;
    }

    // Too long: split on paragraphs, packing them up to the limit.
    let buffer = '';
    for (const para of section.split(/\n\s*\n/)) {
      if (buffer.length + para.length > maxChars && buffer) {
        chunks.push({ text: buffer.trim(), heading });
        buffer = '';
      }
      buffer += para + '\n\n';
    }
    if (buffer.trim()) chunks.push({ text: buffer.trim(), heading });
  }

  return chunks;
}
Prepend the context the chunk lost
This one is small and it consistently outperforms more elaborate techniques. A chunk taken from the middle of a document has lost the information that it belongs to that document, under that heading. Put it back before embedding. Anthropic published a fuller version of the same idea as contextual retrieval, generating a sentence of situating context per chunk with a model rather than templating it from the heading. That costs a generation call per chunk at index time. The cheap templated version below gets a good share of the benefit for nothing, so start there and measure before paying for the elaborate one.
// Embed this, not the bare chunk text.
const embedText = [
  `Document: ${doc.title}`,
  chunk.heading ? `Section: ${chunk.heading}` : '',
  '',
  chunk.text,
]
  .filter(Boolean)
  .join('\n');
A chunk reading "It must be renewed every 12 months" is close to meaningless in isolation and matches almost any question about renewal. The same chunk prefixed with "Document: TLS Certificate Policy / Section: Expiry" is now specific, and it stops competing with the renewal section of nine other documents.
How big should chunks be?
There is no universal answer, but the shape of the tradeoff is consistent:
| Size | Behaviour | Suits |
|---|---|---|
| 200-400 chars | Precise matches, but chunks often lack the context to be understood alone | FAQ entries, definitions, product specs |
| 800-1500 chars | The usual sweet spot for prose documentation | Guides, policies, articles |
| 3000+ chars | Retrieves whole topics, but the specific sentence gets diluted and precision drops | Narrative documents where context matters more than precision |
I start at roughly 1,000 characters with structure-aware splitting, then measure. Which brings up the part that makes all of this tractable.
Measure retrieval separately from generation
The mistake that keeps teams stuck is evaluating the final answer. When the answer is wrong you cannot tell whether retrieval missed or the model mishandled good context, so you tune both at once and learn nothing.
Test retrieval on its own. Write out questions with the chunk that should be returned, then measure how often it appears in the top k.
type Example = { question: string; expectedChunkId: string };

async function recallAtK(examples: Example[], k: number): Promise<number> {
  let hits = 0;
  for (const ex of examples) {
    const results = await search(ex.question, { limit: k });
    if (results.some((r) => r.id === ex.expectedChunkId)) hits++;
  }
  return hits / examples.length;
}

// Compare chunking strategies on the same questions.
console.log('recall@5 ', await recallAtK(examples, 5));
console.log('recall@20', await recallAtK(examples, 20));
The gap between those two numbers tells you what to do next. High recall@20 with low recall@5 means retrieval finds the right chunk but ranks it poorly, which is a reranking problem. Low recall@20 means it is not being found at all, which is a chunking or embedding problem. Those need completely different fixes, and without the two numbers you cannot tell which one you have.
Where does vector search alone fail?
Embeddings are good at meaning and bad at exact tokens. Ask about part number MX-4021-B and the search returns chunks about part numbers generally, because to an embedding model that string is semantically similar to every other product code.
The affected categories are predictable: identifiers and SKUs, error codes, version numbers, people's names, acronyms, and negation. Negation deserves a mention because it is invisible until it bites: "refunds are available" and "refunds are not available" embed to nearly the same vector.
Hybrid search
Run keyword search alongside vector search and combine the results. Postgres does both, so this does not require another system: pgvector documents the hybrid pattern against tsvector, which is the same shape as the query below.
const [semantic, keyword] = await Promise.all([
  db.query(
    `SELECT id FROM chunks ORDER BY embedding <=> $1 LIMIT 30`,
    [toVector(queryVector)]
  ),
  db.query(
    `SELECT id FROM chunks
     WHERE tsv @@ plainto_tsquery('english', $1)
     ORDER BY ts_rank(tsv, plainto_tsquery('english', $1)) DESC
     LIMIT 30`,
    [question]
  ),
]);

const fused = reciprocalRankFusion(
  semantic.rows.map((r) => r.id),
  keyword.rows.map((r) => r.id)
);
Combine by rank position rather than by score. A cosine similarity of 0.82 and a ts_rank of 0.19 are not on the same scale, and averaging them produces a number with no meaning. Reciprocal rank fusion only looks at positions, which is why it works without per-corpus tuning.
Reranking, the step that pays for itself
Vector search compares a question vector to chunk vectors that were computed before the question existed. A reranker reads the question and the chunk together and scores that pair directly. It is far more accurate and far too slow to run over a whole corpus, which is exactly why the two-stage design works: retrieve 20 to 50 cheaply, rerank those, keep the best few.
In practice this is the single highest return change available to most retrieval systems, and it is roughly three lines. If recall@20 is good and recall@5 is not, add a reranker before you touch anything else.
Practical notes that cost me time
Embed the question the same way you embed the chunks. Some models expect an asymmetric setup where queries and documents get different prefixes. Get this backwards and quality degrades noticeably with nothing to indicate why.
Store the model name with every vector. Six months later, when you are deciding whether to upgrade, the index needs to be able to tell you what built it. Mixing vectors from two models in one collection produces silent nonsense rather than an error.
Batch your embedding calls. One request per chunk on a 50,000 chunk corpus is slow, expensive in overhead, and will hit a rate limit. Batches of 50 to 100 are usually the practical sweet spot.
Re-embedding is a migration. Changing the model or the chunking strategy invalidates the whole index. Build the new one alongside the old, compare on your test set, then swap. Doing it in place means your search is broken for the duration and you have no way back.
The order I would work in
Write thirty test questions before writing any retrieval code. Build structure-aware chunking with document and heading context prepended. Measure recall@5 and recall@20. Add a reranker. Add keyword search if your domain contains identifiers. Only then start adjusting chunk sizes, because by that point you can actually see whether a change helped.
Nearly every retrieval system I have seen struggle was skipping the measurement step, and every one of them was tuning the prompt instead. Once retrieval is solid, the remaining work is on the request itself, caching the stable prefix and constraining output, which I covered in LLM API integration.
Frequently asked questions
What chunk size should I use for RAG?
Around 800 to 1500 characters suits most prose documentation. Smaller chunks of 200 to 400 characters give precise matches but often lack the context to be understood alone, which suits FAQ entries and definitions. Chunks over 3000 characters retrieve whole topics but dilute the specific sentence, so precision drops. Start near 1000 with structure-aware splitting, then measure. The number matters less than where you cut. Splitting on headings and paragraph boundaries beats any character count applied blindly, because a chunk that ends mid-sentence embeds badly and reads worse when it reaches the prompt. Treat the size as an upper bound you split within rather than a target you pad to, and let genuinely short sections stay short instead of merging unrelated material to hit a length. Code and tables are the exception to all of this, because both break badly on character counts and want structural splitting instead.
Should I use a similarity score threshold?
No. A cosine similarity of 0.8 does not mean 80% likely to be relevant, and the absolute range varies wildly between embedding models. A fixed threshold silently filters out correct results on one model and nothing at all on another, and it will quietly break the day you change models. Rank the results and cut by position instead: take the top twenty, rerank, keep four. If you genuinely need to detect that nothing relevant exists, so the system can say so rather than answer from noise, get that signal from a reranker score rather than from raw embedding distance. Reranker scores are trained to express relevance directly and are far more comparable across queries than cosine similarity ever is. If you have already shipped a threshold, log what it filters out before removing it, because the results it quietly drops are usually more surprising than expected.
Why does vector search fail on product codes and names?
Embeddings capture meaning rather than exact tokens, so a string like MX-4021-B is semantically similar to every other product code. The affected categories are predictable: identifiers, error codes, version numbers, people names, acronyms and negation. Negation is the one that surprises people, because a chunk saying a feature is not supported embeds close to one saying it is. Run keyword search alongside vector search and combine the two rankings with reciprocal rank fusion, which needs no tuning and no score normalisation between the two systems. Postgres can do both halves, so hybrid search usually costs you one extra query rather than one extra piece of infrastructure. This is the single most common reason a demo works and the real corpus does not. Testing with real identifiers taken from your own corpus, rather than with natural language questions, surfaces this class of failure before your users do.
How do I measure retrieval quality?
Test retrieval separately from generation. Write questions paired with the chunk that should be returned, then measure recall at five and recall at twenty. High recall at twenty with low recall at five means ranking is the problem, so add a reranker. Low recall at twenty means the chunk is not being found at all, which is a chunking or embedding problem and no amount of reranking will rescue it. That split is the whole value of the exercise, because it tells you which half of the pipeline to work on. Thirty hand-written pairs in a JSON file, run in CI, is enough to start and more useful than any framework adopted before you have examples to feed it. Keep that set in version control next to the code, so a change in chunking strategy shows up as a diff in the numbers rather than as a hunch.
Related Articles